AI
promptev agents now cost up to 83% less on large data
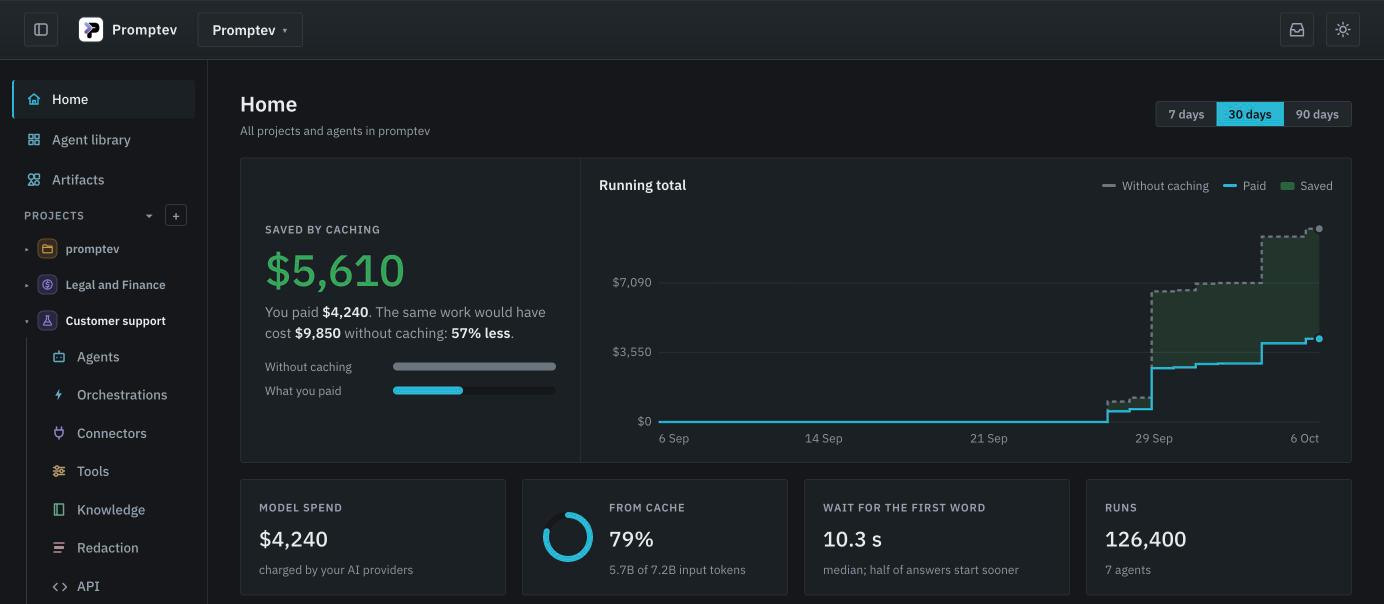
An AI agent pays for every token it reads. When a question needs thousands of records, most agents read all of them, and the bill grows with the data.
Our latest release changes that for every promptev agent. This article gives the numbers.
The short answer
| Test | Cost per answer | Tokens per answer |
|---|---|---|
| Questions that need 8,946 records | 83% lower | 78% fewer |
| Questions over 1,000,000 records | 58% lower | 35% fewer |
| Questions that need 100,582 records | $0.009 | 39,617 |
How we measured
- Same questions, two versions. “Before” is promptev before the release. “After” is promptev with it. Nothing else differs.
- Two models: gpt-5.4-mini and gemini-2.5-flash.
- Two or three runs for each question, on each model.
- Cost is the model provider’s price for the tokens of the whole run.
Test 1: questions that need 8,946 records
The questions ask for totals, counts, the largest value and the busiest day across 8,946 order records.
| Before | After | |
|---|---|---|
| Tokens per question | 175,255 | 38,813 |
| Cost per question | $0.0626 | $0.0106 |
| Time per question | 22.2 seconds | 13.0 seconds |
Test 2: questions over 1,000,000 records
The data is 1,000,000 records in 75 tables. The questions are a mix: totals, top lists, one record found by its number, and long lists.
| Before | After | |
|---|---|---|
| Tokens per question | 66,938 | 43,405 |
| Cost per question | $0.0215 | $0.0091 |
The largest gain was on the questions with the most data. One question, a full day of orders, fell from 367,973 tokens to 57,118.
Test 3: questions that need 100,582 records
This is test 1 with eleven times the records.
| After | |
|---|---|
| Tokens per question | 39,617 |
| Cost per question | $0.0093 |
| Time per question | 14.8 seconds |
The agent used about the same number of tokens as in test 1. More data did not mean a larger bill.
Where the saving is small
- Small questions. A question with one short answer does not get cheaper. The saving comes from questions that need a lot of data.
- Time on test 2. It was 12.8 seconds before and 13.2 seconds after.
- Your numbers will differ. They depend on your tools, your data and your model.
What this means for you
- You do nothing. The release is on for every promptev agent, on every plan.
- It works with your tools. APIs, MCP servers, connected data and spreadsheets.
- Your model keys, your bill. promptev agents run on your own model keys, so fewer tokens is a lower bill from your provider.
Start free with 2,500 credits and try it on your own data.
Faisal Saeed is Founder & CEO of promptev, building next-gen context engineering infrastructure that enables teams to orchestrate, scale, and deploy production-ready generative AI systems with confidence.